Biology › Nucleic acids, genomes and protein synthesis › The genetic code and transcription
The genetic code and transcription
Four bases have to specify twenty amino acids, and they do it in threes. The rules that follow, 64 triplets for 20 amino acids, no overlaps, and almost the same table in every organism alive, explain a great deal about how mutations behave and why genetic engineering works at all.
Before this DNA and RNA structure · Complementary base pairing · The nuclear envelope and nuclear pores
COMMON MISCONCEPTION
The genetic code is degenerate, so it is a wasteful system evolution has not got round to tidying up.
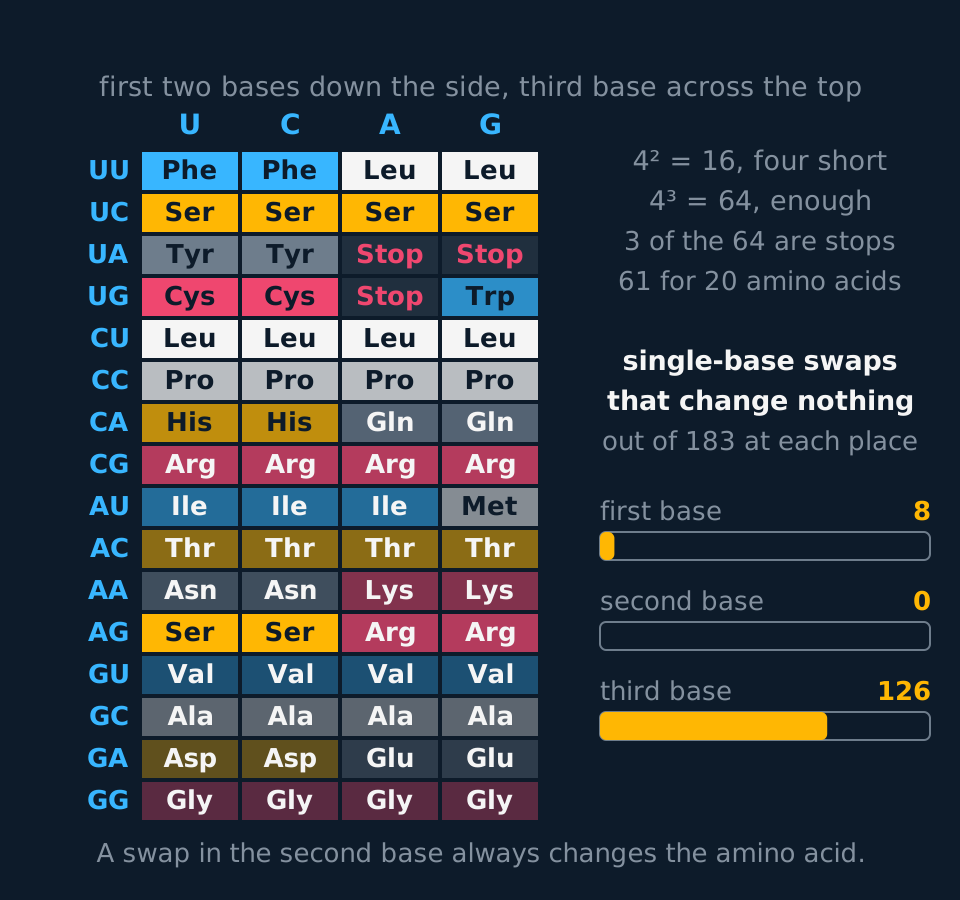
Because the genetic code is degenerate, several codons specify the same amino acid, usually differing only in the third base. A substitution at that position can therefore leave the amino-acid sequence unchanged, which is what a silent mutation is.
What you should be able to do
- State the four properties of the genetic code and explain a consequence of each.
- Explain, with numbers, why the code has to be read in threes rather than ones or twos.
- Distinguish exons from introns, and a gene from the genome.
- Describe transcription in sequence, naming the enzyme, the strand used and the bonds involved.
- Explain what splicing does and why one gene can give rise to more than one polypeptide.
- Explain why many base substitutions change nothing about the protein.
Four properties, and what each one makes possible
The genetic code is the relationship between triplets of bases and amino acids. Four statements describe it, and each has a consequence you can be asked about directly.
| Property | What it means | What follows |
|---|---|---|
| Triplet | Three bases specify one amino acid | 64 possible triplets for 20 amino acids, so there is capacity to spare |
| Degenerate | Most amino acids have more than one triplet | Many base substitutions produce no change in the protein |
| Non-overlapping | Each base belongs to one triplet only | An insertion or deletion not divisible by three shifts every triplet after it |
| Universal | Almost all organisms read the same triplets the same way | A human coding sequence, freed of its introns and given bacterial control signals, directs a bacterium to make the human protein |
Describe the drawing
The sixty-four messenger RNA triplets set out as sixteen rows of four, the first two bases down the side and the third base across, with every cell coloured by the amino acid it specifies and the three stop triplets marked. Eight of the sixteen rows are a single colour all the way across, so for those the third base makes no difference at all. Beside the table, three bars count the single-base changes that leave the protein unaltered: eight at the first base, none at the second and a hundred and twenty-six at the third, out of a hundred and eighty-three possible at each position.
Why three and not two
Show, using numbers, why a code based on pairs of bases could not specify twenty amino acids, and state how many triplets are spare once every amino acid has one.
Show the working
There are four bases. A code of one base gives 4¹ = 4 combinations, which is nowhere near enough. A code of two bases gives 4² = 16 combinations, still four short of the twenty amino acids that need specifying.
A code of three bases gives 4³ = 64 combinations, which is comfortably enough. Three of the 64 are stop signals, leaving 61 that specify amino acids.
Sixty-one triplets sharing twenty amino acids means 41 more than the minimum, and that surplus is what degeneracy consists of. Leucine, serine and arginine have six triplets each; methionine and tryptophan have only one.
State universality carefully. The code is very nearly universal rather than absolutely so: mitochondria and a few protoctists interpret a small number of triplets differently. Use 'universal' when naming the property and 'almost universal' where precision is required. The consequence is the same in both cases: because a bacterium interprets human triplets as a human cell does, human insulin has been manufactured in E. coli since 1982.
- Codon
- A sequence of three bases in mRNA that specifies one amino acid or a stop signal.
- Degenerate
- Describing a code in which most amino acids are specified by more than one triplet.
- Non-overlapping
- Describing a code in which each base is part of one triplet only and triplets are read in sequence.
Genes, exons and introns
A gene is a sequence of DNA bases that codes for a polypeptide, or for a functional RNA molecule such as a tRNA. Its position on a chromosome is its locus. The genome is the complete set of DNA in a cell, and the proteome is the full range of proteins that cell can produce, a set that differs between cell types; which of those proteins are present at any moment depends on which genes are being expressed.
In eukaryotes a gene is not one continuous coding sequence. It is broken into exons, which are the parts that end up represented in the finished mRNA, separated by introns, which do not. Introns can be long: some human genes are more than 95% intron by length. Prokaryotic genes almost never contain introns, a few self-splicing exceptions aside, which is one of several reasons a human gene cannot simply be pasted into a bacterium and expected to work.
- Gene
- A sequence of DNA bases coding for a polypeptide or a functional RNA.
- Exon
- A section of a gene that is represented in the mature mRNA.
- Intron
- A non-coding section of a gene, transcribed into pre-mRNA and then removed before the mRNA leaves the nucleus.
- Genome
- The complete set of DNA in a cell, including the DNA that does not code for polypeptides.
A large proportion of eukaryotic DNA is non-coding: introns, repeated sequences between genes, and regions involved in switching genes on and off. The evidence does not support calling all of it useless, and questions increasingly expect you to know that non-coding does not mean functionless.
Transcription, step by step
Transcription is the copying of one gene into mRNA, and it happens in the nucleus because that is where the DNA is. The enzyme is RNA polymerase, not DNA polymerase, which does a different job in a different process, and confusing the two is one of the quickest ways to lose a whole answer.
Describe the drawing
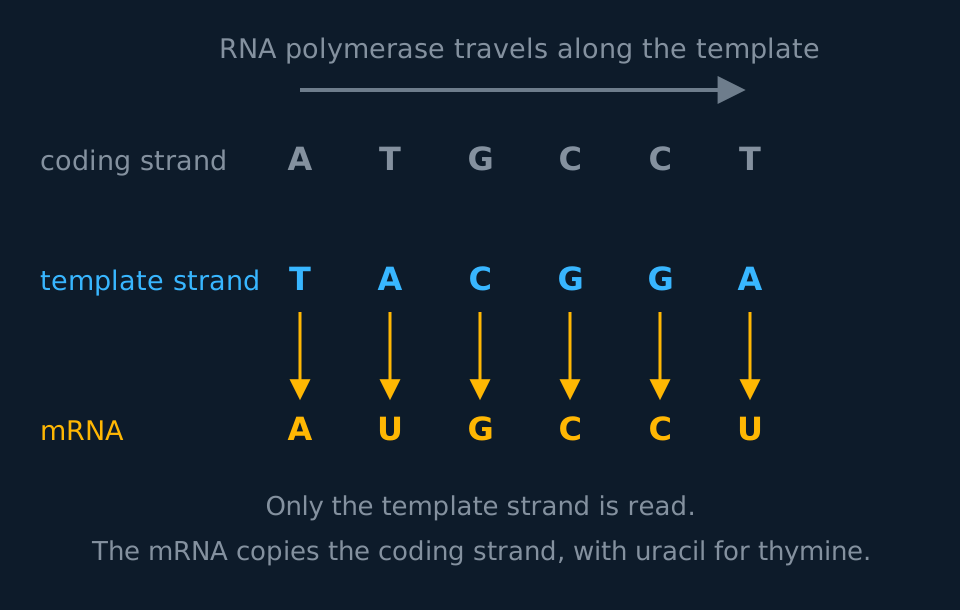
Three rows of letters. The top row is a DNA coding strand reading A T G C C T, the middle row the template strand reading T A C G G A beneath it, and the bottom row the messenger RNA reading A U G C C U, with an arrow from each template base down to the RNA base it specifies. An arrow across the top shows RNA polymerase moving along the template.
In order, then. RNA polymerase binds to a promoter region at the start of the gene and unwinds a short section of the double helix, breaking the hydrogen bonds between the paired bases. Only one of the two exposed strands is used: the template strand. Free RNA nucleotides in the nucleoplasm align against it by complementary base pairing, with uracil pairing to adenine wherever thymine would have gone. RNA polymerase joins the aligned nucleotides by condensation, forming phosphodiester bonds, and moves along the gene as it works. Behind it, the two DNA strands re-form their hydrogen bonds and the helix rewinds. When the enzyme reaches a terminator sequence at the end of the gene it detaches, and the finished pre-mRNA is released. The terminator is a transcription signal in the DNA, a different thing from the stop codons translation reads in the mRNA.
The strand that is not transcribed is the coding strand. Its sequence is the same as that of the mRNA, with T wherever the mRNA has U. Pearson Edexcel calls the coding strand the sense strand and the template strand the antisense strand; Cambridge International calls them the non-transcribed and transcribed strands. Where a question supplies the coding strand, write the mRNA by replacing every T with U. Where it supplies the template strand, take the complement first.
Splicing of pre-mRNA
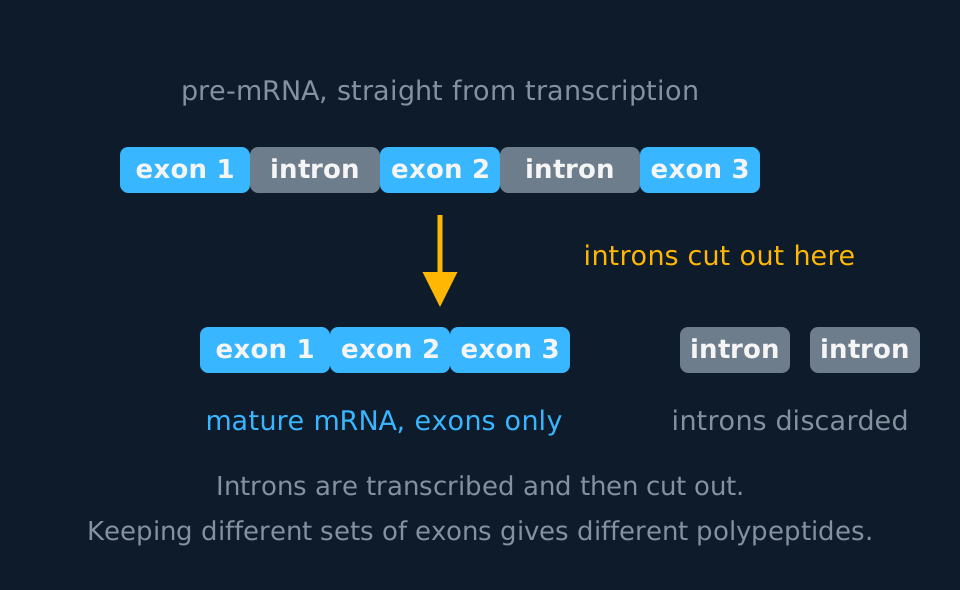
The pre-mRNA that RNA polymerase produces is a copy of the whole gene, introns included. Before it can be used it goes through splicing: structures called spliceosomes cut the introns out and join the exons together, producing mature mRNA. Only then does the molecule leave the nucleus through a nuclear pore and travel to a ribosome.
Describe the drawing
A bar representing pre-messenger RNA divided into five blocks: exon one, an intron, exon two, a second intron and exon three. An arrow downward leads to a shorter bar holding only exon one, exon two and exon three joined end to end in the same order, with the two intron blocks drawn separately to one side as discarded.
Splicing is not always done the same way on the same transcript. Under alternative splicing, different combinations of exons are retained, so one gene gives rise to several different mRNA molecules and therefore several different polypeptides. This is a large part of why humans manage a proteome of well over 100,000 proteins from around 20,000 protein-coding genes.
- Pre-mRNA
- The immediate product of transcription in a eukaryote, containing both exons and introns.
- Splicing
- The removal of introns from pre-mRNA and the joining of exons to produce mature mRNA.
Degeneracy, silent mutations and frame shifts
The mRNA codon GAA specifies glutamic acid. Changing its third base to G gives GAG, which also specifies glutamic acid. The DNA has changed, the mRNA has changed, and the amino-acid sequence has not. A substitution of that kind is a silent mutation, and it is common because triplets specifying the same amino acid usually differ in the third base.
Compare that with a deletion. Remove one base and every triplet downstream is read from a new starting point, because the code is non-overlapping and read strictly in threes from a fixed start. A single deletion near the beginning of a gene can therefore change every amino acid after it and usually produces a premature stop codon, giving a shortened and non-functional polypeptide. Attribute each outcome to the property of the code responsible: degeneracy for the silent substitution, non-overlapping reading for the frame shift.
TRY IT: Comparing a substitution with a deletion
A section of the coding strand of a gene reads TTA CGA GAA CCT. One sample has the fourth base changed from C to A. Another sample has the fourth base deleted altogether. Count along the sequence before you start. Explain why the second is likely to be far more damaging than the first, without needing a codon table.
Check your answer
The fourth base is the C at the start of the second triplet, so the substitution changes one triplet and nothing else. CGA becomes AGA, so at worst one amino acid in the finished polypeptide is different, and because the code is degenerate the new triplet may well specify the same amino acid anyway. Even if it does not, a single amino acid change in a region away from the active site or binding site often leaves the protein working normally.
The deletion is different in kind. The code is non-overlapping and read in threes from a fixed start, so removing one base pulls every subsequent base one place forward. Every triplet from that point on is read differently, which is a frame shift, and the amino acid sequence after the deletion bears no relation to the original.
A shifted reading frame also produces stop codons at unpredictable positions, so the polypeptide is usually shortened as well as altered in sequence, and rarely folds into a functional shape.
In the exam
- Use the terms 'triplet', 'degenerate', 'non-overlapping' and 'universal' by name rather than paraphrases such as 'three letters at a time'.
- Name RNA polymerase as the enzyme for transcription, not DNA polymerase.
- State that hydrogen bonds are broken to expose the template and that phosphodiester bonds are formed along the new RNA. Include both.
- mRNA contains U, not T. Check any sequence written before moving on.
- Where the coding strand is given, substitute U for T. Where the template strand is given, take the complement first. Identify which strand is supplied.
- Attribute silent mutations to degeneracy and frame shifts to the non-overlapping code. Name the property as well as the effect.
Check yourself
A biotechnology company wants a human gene expressed in a bacterium. They isolate the gene directly from a human chromosome and insert it into E. coli, but no functional human protein is produced. Suggest why, and what they should have used instead.
Answer
A gene taken straight from a human chromosome contains introns. Bacteria do not carry out splicing, because their own genes almost never contain introns and they have no spliceosomes.
The bacterium therefore transcribes the whole inserted sequence, introns included, and translates it as though every base were coding. The introns are read in the reading frame that happens to follow, producing wrong amino acids and almost certainly premature stop codons, so no functional human protein appears.
The fix is to start from mature mRNA rather than from the chromosome. Isolate the mRNA from a human cell that expresses the gene heavily, then use reverse transcriptase to make a DNA copy of it. Because the introns have already been spliced out of that mRNA, the resulting DNA is a continuous coding sequence the bacterium can handle.
The universality of the code is not in question here: the bacterium interprets each triplet as a human cell does. The failure is caused by the introns, not by the code.
Questions
Question 15 marks
Describe how a molecule of pre-mRNA is produced from a gene in the nucleus of a eukaryotic cell.
Mark scheme
- B1 RNA polymerase binds to a promoter region at the start of the gene
- B1 the enzyme unwinds a short section of the double helix, breaking the hydrogen bonds between the paired bases
- B1 only one of the two exposed strands, the template strand, is read
- B1 free RNA nucleotides align against the template by complementary base pairing, with uracil pairing to adenine wherever thymine would have gone
- B1 RNA polymerase joins the aligned nucleotides by condensation into phosphodiester bonds, moving along the gene until it reaches a terminator sequence and releases the pre-mRNA
Question 24 marks
Explain why a mature mRNA molecule is shorter than the gene it was transcribed from, and explain how one gene can give rise to more than one polypeptide.
Mark scheme
- B1 the pre-mRNA is a copy of the whole gene, introns included
- B1 spliceosomes cut the introns out and join the exons together, so the introns are not represented in the mature mRNA
- B1 in alternative splicing, different combinations of exons are retained in the mature mRNA
- B1 so several different mRNA molecules, and therefore several different polypeptides, can come from the same gene
Question 34 marks
A single base is inserted into the coding sequence of a gene close to its start. The polypeptide produced is much shorter than normal and its amino acid sequence bears no relation to the original beyond the point of insertion. Suggest why, referring to two properties of the genetic code.
Mark scheme
- B1 the code is read in threes from a fixed starting point and is non-overlapping, so each base belongs to one triplet only
- B1 inserting a base pushes every subsequent base one place along, so every triplet after the insertion is read differently, which is a frame shift
- B1 the amino acid sequence after that point is therefore completely altered rather than altered in one place
- B1 a shifted reading frame produces stop codons at positions where there were none, so translation ends early and the polypeptide is short
Question 44 marks
Compare the coding strand of a gene with the template strand, referring to which one is transcribed and how each one's sequence relates to the mRNA produced.
Mark scheme
- B1 the template strand is the strand that RNA polymerase actually reads and copies, whereas the coding strand is not transcribed at all
- B1 the mRNA produced is complementary to the template strand, base for base, whereas the mRNA has the same sequence as the coding strand except that every thymine in the coding strand is replaced by uracil in the mRNA
- B1 given the coding strand, the mRNA sequence can be written directly by substituting U for T, whereas given the template strand, the complementary sequence must first be taken before substituting U for T
- B1 only the template strand is exposed to complementary base pairing with the incoming RNA nucleotides during transcription, so only its sequence, not the coding strand's, physically determines which bases are added
Question 54 marks
A textbook describes introns and other non-coding DNA as 'junk DNA' with no function. Evaluate this description, using what you know about non-coding DNA.
Mark scheme
- B1 for: introns and much other non-coding DNA does not code for a polypeptide, and it is removed from pre-mRNA by splicing before the mature mRNA is used, so it plays no part in specifying the sequence of the finished protein
- B1 against: a large proportion of eukaryotic DNA is non-coding, including introns, repeated sequences between genes and regions involved in switching genes on and off, and several of these regions have known regulatory or other roles rather than none at all
- B1 against: alternative splicing depends on retaining different combinations of exons from the same pre-mRNA, so which sequence is treated as exon and which as intron contributes to which mRNA molecules, and hence which polypeptides, a gene can produce
- B1 judgement: 'non-coding' is not the same claim as 'functionless', and describing all such DNA uniformly as junk overstates how much of it has been shown to do nothing, even though a function for every stretch of it has not been demonstrated either
Question 64 marks
A student says that the genetic code being degenerate, with most amino acids specified by more than one triplet, shows it is a wasteful system that evolution has simply not got round to tidying up. Discuss this claim.
Mark scheme
- B1 for the student's claim: sixty-one triplets are shared between only twenty amino acids, which is forty-one more than the minimum needed, so in terms of the sheer number of triplets in use there is apparent redundancy
- B1 against: triplets sharing an amino acid tend to differ mainly in their third base, so a substitution mutation at that position is often silent, leaving the protein completely unchanged rather than harming it
- B1 against: because degeneracy makes many mutations silent, it reduces how often a random copying error or mutagen actually changes the protein an organism produces, which is a protective effect rather than a wasted one
- B1 judgement: describing the redundancy as unused waste ignores this protective consequence; degeneracy is better understood as a feature that has been retained because it reduces the impact of mutation, not as an oversight evolution failed to remove
Question 73 marks
The coding strand of a short section of a gene reads GAT CCA TTG. Give the base sequence of the template strand, written base for base beneath the coding strand, give the base sequence of the mRNA transcribed from this section, and give the rule that relates the mRNA sequence to the coding strand.
Mark scheme
- B1 template strand CTA GGT AAC, each base complementary to the coding strand
- A1 mRNA GAU CCA UUG
- B1 the mRNA matches the coding strand, with uracil in place of every thymine
Question 83 marks
A base substitution changes the third base of one mRNA codon, and the polypeptide produced is completely unchanged. Explain how this is possible.
Mark scheme
- B1 the genetic code is degenerate: most amino acids are specified by more than one triplet
- B1 triplets sharing an amino acid tend to differ in the third base, so the new codon can specify the same amino acid as the old one
- B1 the primary structure is then identical, so the polypeptide is unchanged, and the substitution is called silent
Question 93 marks
State what is meant by a gene, state what is meant by its locus, and state how the genome differs from the proteome.
Mark scheme
- B1 a gene is a sequence of DNA bases that codes for a polypeptide, or for a functional RNA molecule such as a tRNA
- B1 the locus of a gene is its specific position on a chromosome
- B1 the genome is the complete set of DNA in a cell, whereas the proteome is the full range of proteins that cell is able to produce
Question 103 marks
Describe the difference between an exon and an intron, and describe what happens to each during splicing.
Mark scheme
- B1 an exon is a section of a gene that ends up represented in the mature mRNA, whereas an intron is a non-coding section that does not
- B1 the pre-mRNA produced by transcription contains both exons and introns, since it is a copy of the whole gene
- B1 spliceosomes cut the introns out of the pre-mRNA and join the exons together, producing the mature mRNA that leaves the nucleus
Question 113 marks
Explain why the terminator sequence at the end of a gene and a stop codon in an mRNA molecule are two different things, even though both are commonly called 'stops'.
Mark scheme
- B1 the terminator is a sequence in the DNA of the gene itself, recognised by RNA polymerase, which causes the enzyme to detach and release the finished pre-mRNA, ending transcription
- B1 a stop codon is a triplet in the mature mRNA, read by the ribosome during translation, which causes translation of the polypeptide to end
- B1 the terminator therefore acts on RNA polymerase and finishes making the RNA copy, while a stop codon acts on the ribosome and finishes making the polypeptide
Question 123 marks
Mitochondrial DNA interprets a small number of triplets differently from nuclear DNA in the same cell. Suggest what this shows about the claim that the genetic code is universal, and suggest why the near-universality of the code across most organisms is still significant for genetic engineering.
Mark scheme
- B1 the code is not absolutely universal, since mitochondria interpret a few triplets differently from the interpretation used by the nuclear genome of the very same cell, so 'universal' should be read as 'almost universal'
- B1 despite that exception, the code is read the same way across the great majority of triplets and the great majority of organisms, including between organisms as different as bacteria and humans
- B1 that near-universal agreement is what allows a gene taken from one species to be transcribed and translated correctly by the machinery of an unrelated species, which is what genetic engineering that inserts a human gene into a bacterium depends on
Question 132 marks
State what is meant by saying that the genetic code is degenerate, and state what is meant by saying that it is non-overlapping.
Mark scheme
- B1 degenerate: most amino acids are specified by more than one triplet
- B1 non-overlapping: each base belongs to one triplet only, and the triplets are read one after another
Question 142 marks
DNA uses four bases read in triplets. Calculate the total number of different triplets, and the number left to specify amino acids once the stop signals are set aside.
Mark scheme
- M1 the number of triplets is 4 raised to the power 3, which is 64
- A1 three of the 64 are stop signals, leaving 61 that specify amino acids
Question 152 marks
Name the enzyme that carries out transcription, and name the structures that remove introns from pre-mRNA.
Mark scheme
- B1 RNA polymerase, which is not the enzyme that replicates DNA
- B1 spliceosomes, which cut the introns out and join the exons together
Worth remembering
- Triplet, degenerate, non-overlapping, universal, and a consequence for each.
- 4³ = 64 triplets, 61 coding and 3 stop, for 20 amino acids.
- RNA polymerase transcribes; only the template strand is read.
- The mRNA matches the coding strand with U in place of T.
- Splicing removes introns and joins exons; alternative splicing lets one gene give several polypeptides.
CHECK YOUR PROGRESS
Rate how confident you are with each objective for this lesson. Ratings are saved in this browser, on this device, unless you sign in.
- State the four properties of the genetic code and explain a consequence of each.
- Explain, with numbers, why the code has to be read in threes rather than ones or twos.
- Distinguish exons from introns, and a gene from the genome.
- Describe transcription in sequence, naming the enzyme, the strand used and the bonds involved.
- Explain what splicing does and why one gene can give rise to more than one polypeptide.
- Explain why many base substitutions change nothing about the protein.
Open the full revision checklist to see every objective in the curriculum in one place.
Practise this lesson
WORKBOOK
The questions from this topic, on paper with room to work, and a separate book of mark schemes. Free to use; please do not redistribute or sell.
Used later in Monohybrid inheritance and genetic diagrams · Classification, phylogeny and molecular evidence